Regular Expressions for Adding Commas to Numbers
When displaying currency, a common requirement is to format raw numbers into a more human-readable form, such as:
- 1234567 → 1,234,567
- 10000 → 10,000
In front-end development, we can accomplish this in several ways:
- Using
Intl.NumberFormat(Older browsers might not support it and would require a polyfill) - Using regular expressions with
.replace
There has been extensive discussion on Stack Overflow regarding this topic, with the most popular thread likely being: How to print a number with commas as thousands separators in JavaScript
While there are many different solutions, their general shape usually boils down to these two:
const reg1 = /\B(?=(\d{3})+$)/
const reg2 = /(\d)(?=(\d{3})+$)/
This article will attempt to explain the differences between these two regular expressions and how they actually execute. Finally, we will run some benchmarks to compare their performance.
Introduction
Before diving in, there are a few important concepts that need to be understood first: positive lookahead, negative lookahead, and word boundary. These are concepts that are less commonly encountered when first learning regular expressions, but they are actually quite powerful.
Positive Lookahead and Negative Lookahead
In regular expressions, positive lookahead is represented by the syntax ?=. Taking a(?=b) as an example, this regular expression means: match a only if it is immediately followed by b. It is particularly important to note that ?= itself does not consume any characters in the match; in other words, this regex only matches a.
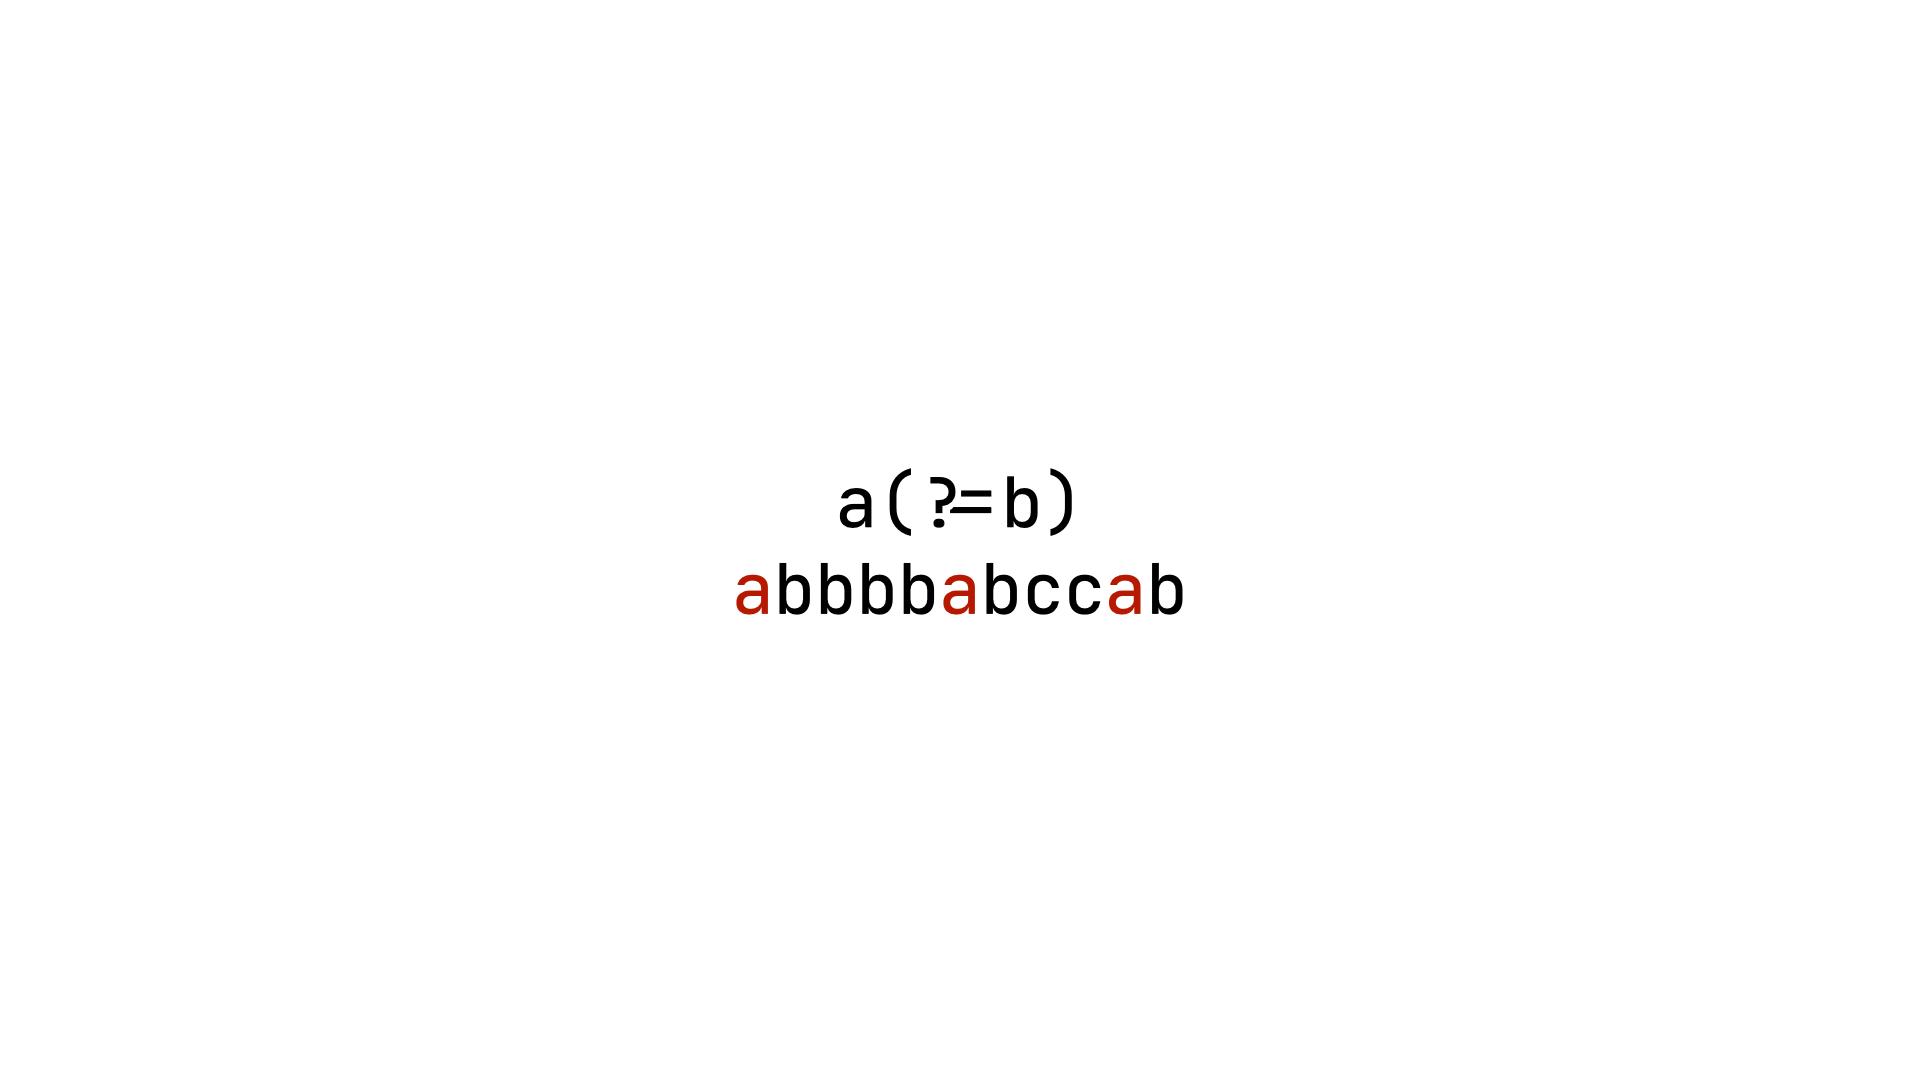
As shown in the image above, only a is matched in the regex.
Lookahead syntax can accept any valid regular expression, not just single characters. For example: ,(?=(?:\d{3})+$) means matching a comma , that is followed by one or more sequences of 3 consecutive digits right up to the end of the string.

Negative lookahead is represented by ?!. As the opposite of positive lookahead, a(?!b) matches a only if it is not immediately followed by b.
It is worth noting that both positive and negative lookaheads are zero-length assertions. This means they do not match any actual characters on their own, so their match length is 0—acting somewhat like an anchor. If you write (?=a) without any preceding characters, this is the result:

You will notice that although the match succeeded, the match length is 0, located in the space between characters.
Returning to the regular expressions mentioned at the beginning:
/\B(?=(\d{3})+$)/ and /(?=(\d{3})+$)/ are quite similar in meaning (though with a few subtle differences). Why are these two expressions similar? We will introduce \b and \B below.
What \b and \B Mean
\b
In regular expressions, uppercase and lowercase letters typically represent opposite meanings. For example, \d matches digits, while \D matches non-digits. Let’s first understand what \b means by referencing the MDN documentation:
A word boundary matches the position where a word character is not followed or preceded by another word-character. Note that a matched word boundary is not included in the match. In other words, the length of a matched word boundary is zero.
To understand how a word character is defined, we also need to understand \w, which is defined as:
Contains alphanumeric characters and underscores, equivalent to
[A-Za-z0-9_].
Now that we know what \w is, let’s look at what “a word character is not followed or preceded by another word-character” means. \b occurs in the following situations (to avoid confusion, we will consistently use “word character” to represent \w):
- At the beginning of a word character sequence
- Between a word character and a non-word character
- At the end of a word character sequence
Looking directly at the image should make it clearer:

You can also think of it literally as a word boundary—the edges surrounding words. Again, it must be emphasized: without adding other characters, \b itself is a zero-width match, so its matched length is always 0, but that does not mean nothing matched.
Do not confuse this with cases where a character is included, such as d\b, which matches the character d when it is followed by a word boundary. In this scenario, the character d is actually consumed:

\B
\B represents the negation of \b, which means a non-word boundary position. What counts as a non-word boundary? Any position not marked with an arrow in the image above.

How to Properly Parse Regular Expressions
Understanding regular expressions naturally requires accumulated experience. However, when using them in development, having a solid mental model is very helpful. A regular expression can be viewed as state transitions in a finite state machine. For example, \d+ can be illustrated like this:

Generally, you might need to include an initial state (for instance, if non-digits are inputted, it should not transition to state 0), but the core idea is what matters. Put the possible input characters on the arrows and determine whether to transition to the next state. If the state reached is a terminal state, the match is accepted.

Dissecting the Expressions
Method 1: Matching Using Zero-Length Assertions
Now that we have covered the necessary background knowledge, we can finally begin our breakdown. Let’s look at the first pattern: /\B(?=(\d{3})+$)/g
The leading \B matches a non-word boundary position. Next, looking at the regex inside (?=), (\d{3})+ matches one or more groups of 3 consecutive digits, such as 333, 666, 123, etc. Looking at the subsequent part, \d matches a single digit. Putting the entire meaning together: match a non-word boundary followed by one or more groups of 3 consecutive digits leading directly to the end of the string.
Here, the interesting part is the trailing (\d{3})+$. This regex requires the length of the matched trailing sequence to be a multiple of 3 and reach the very end of the string. For example, 123456 has a length that is a multiple of 3, whereas 12345 matches one \d{3} but does not end there, so it is not considered a match.
By taking advantage of this property combined with the clever use of \B, for the number 1000000, two positions will be matched:

Therefore, when calling .replace, you can write:
"1000000".replace(/\B(?=(\d{3})+$)/g, ",");Based on the match results in the image above, , will be inserted at these two positions, turning it into 1,000,000. This is why this regular expression does not require using $1,: both \B and (?=) are zero-length matches, so the match length is 0.
You can observe the matching process in the video below. The number of match attempts here is just for reference—behavior may vary across languages and some intermediate steps are omitted, but the general flow looks roughly like this:
Method 2: Matching Digits That Should Be Followed by a Comma
/(\d)(?=(\d{3})+$)/
From here, you can see that aside from \B being removed and \d being added, the overall structure is quite similar. However, there is one key difference: \d actually consumes the digit. The final result looks like this:
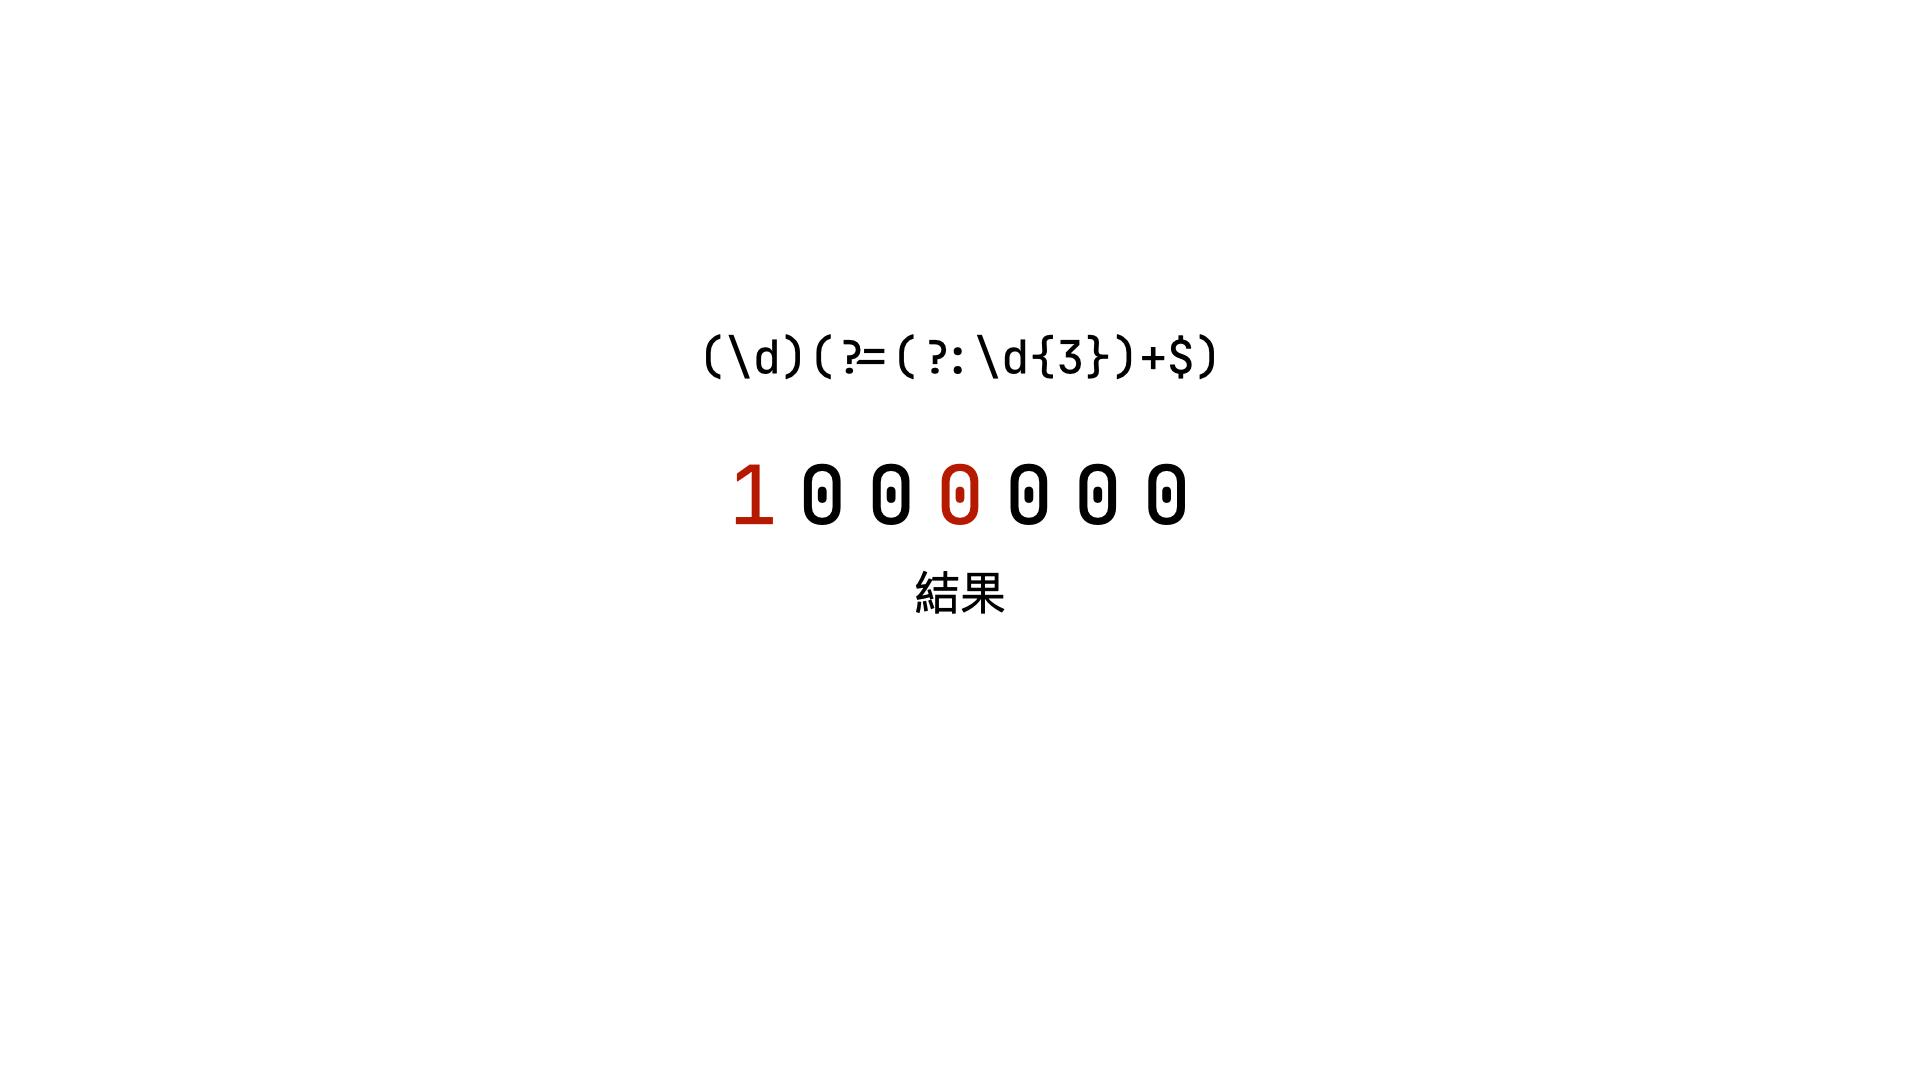
(In the image, ?: is added to indicate a non-capturing group, but the result is the same.)
Personally, I make it a habit to use ?: whenever a grouped value will not be reused, as it makes the pattern easier to read for others and my future self.
The overall process looks roughly like this (omitting intermediate failed match attempts):
Therefore, in JavaScript, you would write:
"1000000".replace(/(\d)(?=(\d{3})+$)/g, "$1,"); // Notice the $1 hereThe $1 here is crucial because we need to put the matched character back in. If you only replace with ,, it would end up looking like this: ,00,000.
Other Considerations and Approaches
Both of the regular expressions above use (?=(\d{3})+$) as the matching condition. However, in practice, numbers may also contain decimal points, meaning something like 1000.12 will not match successfully.
In that case, the expression may need to be modified to handle decimals—for instance, by adding \b as a word boundary so that the match stops at the decimal point.
Additionally, browser APIs support Intl.NumberFormat, which works right out of the box. For usage details, refer to the MDN documentation:
new Intl.NumberFormat('ja-JP', { style: 'currency', currency: 'JPY' }).format(number);Performance and Other Thoughts
Since the output is identical, the remaining considerations come down to readability and performance.
In terms of readability and usability, Intl.NumberFormat is naturally the best choice—MDN’s step-by-step documentation is clear and easy to follow.
The only thing to watch out for is performance. Here is a benchmark test run on jsbench. You can see that Intl.NumberFormat is nearly twice as slow. My guess is that loading i18n data and handling locale-specific number conversions requires more overhead?

Additionally, matching with zero-length assertions is about twice as fast as matching with \d, likely due to the nature of zero-length assertions. However, note that expressions like (\d{3})+ that contain + perform matching via backtracking—matching as much as possible first. For expressions like .+123, the engine will match as much as it can and only backtrack when a match fails. Heavy backtracking causes performance bottlenecks in regular expressions, so be cautious when using similar patterns.
In practice, we can use requestIdleCallback to defer the initialization of Intl.NumberFormat to avoid impacting performance, or wrap the logic in a custom function so that it only initializes when invoked by other files. This should help prevent performance issues.
Alternative Approaches
The regular expressions above rely primarily on lookahead assertions. What if we implemented this with a loop ourselves? Here, I rewrote /(\d)(?=(?:\d{3})+\b)/g as:
let digits = number.toFixed(2).toString()
let matcher = /(\d)(?=(?:\d{3})+\b)/g

while (matcher.test(digits)) {
  let first = digits.slice(0, matcher.lastIndex);
  let second = digits.slice(matcher.lastIndex);
  digits = first + "," + second
}
And a more intuitive approach, updating one segment per iteration:
let digits = number.toFixed(2).toString()
let matcher = /(\d+)(\d{3})/

while (matcher.test(digits)) {
  digits = digits.replace(matcher, "$1,$2");
}
Let’s look at the benchmark results again:
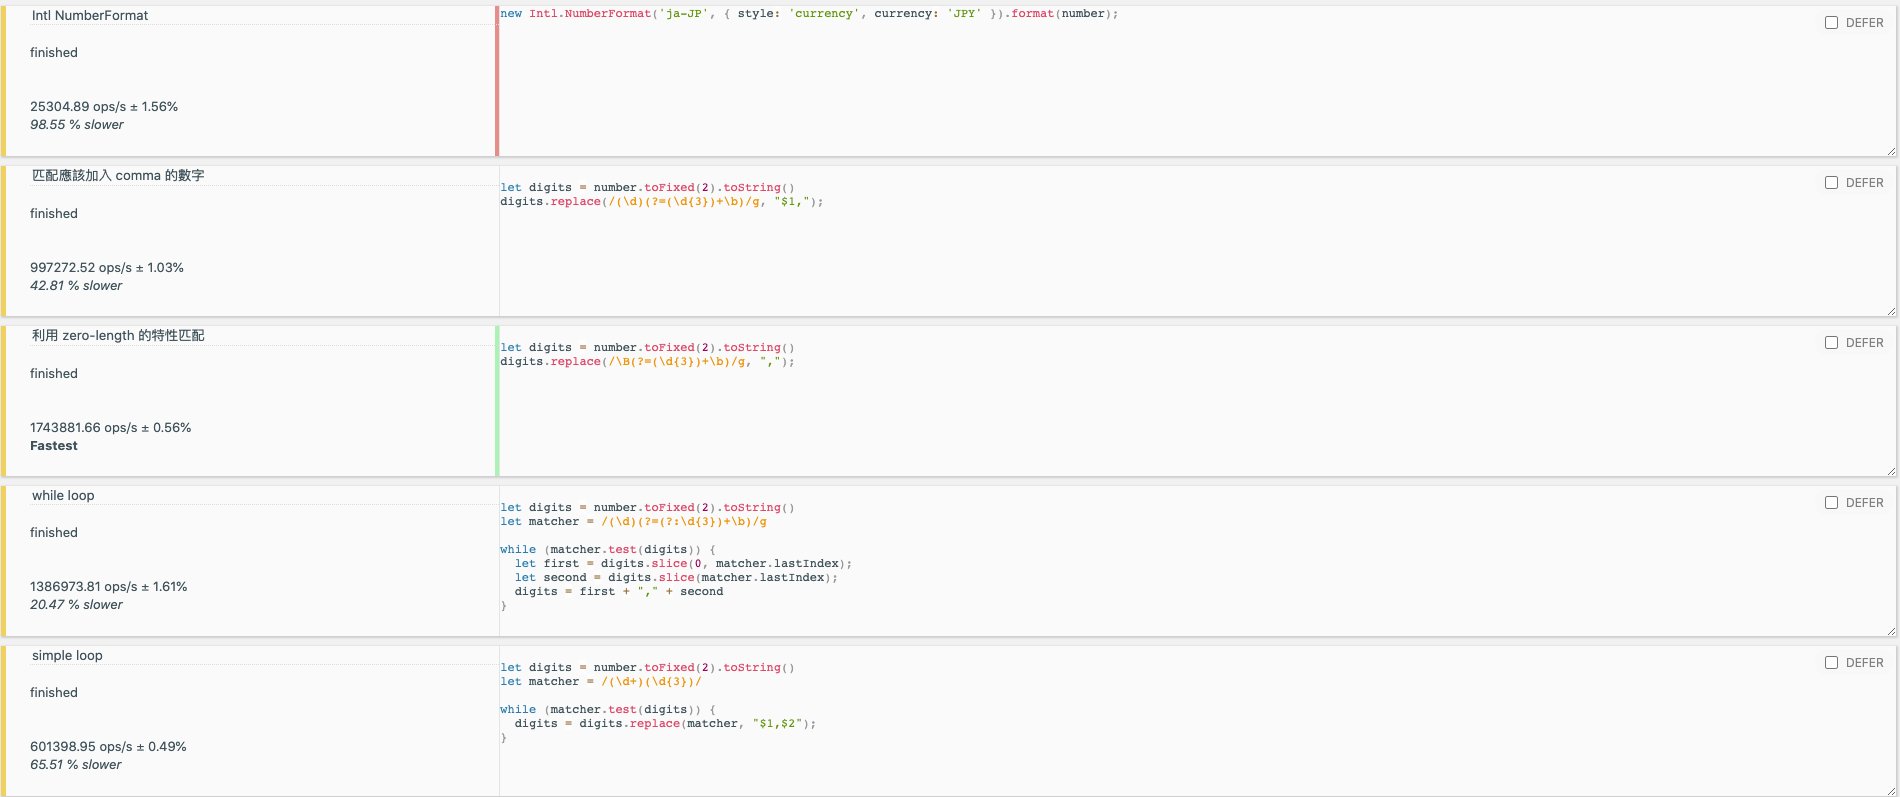
| Name | Ops/s | |
|---|---|---|
Zero-length /\B(?=(\d{3})+\b)/g | 1778943 ops/s fastest | |
| Matching using zero-length assertions (without \B) | 1712701 ops/s 3.72% slower | |
| while loop | 1371453 ops/s 22.91% slower | |
| simple loop | 597173.88 ops/s 66.43% slower | |
Intl.NumberFormat | 25304.89 ops/s 98.55% slower |
The fastest approach remains the zero-length match, followed by the while-loop, with Intl.NumberFormat being the slowest. If you are interested in the benchmark results, feel free to try it out via the link.
Epilogue
There is a lot to discuss when it comes to regular expressions. lookahead and word boundary are relatively less frequently discussed concepts, so I compiled them here. Many of these concepts are detailed extensively in MDN documentation, and Regex101 is a great tool for visualizing regular expressions, complete with detailed side explanations.
Still, even though regular expressions are convenient and powerful, they are undeniably difficult to read!
Related Resources
Related Posts
- Recreating My Room with Three.js Using React Three Fiber, I brought my real room into the browser—turning physical objects into an interactive table of contents, and using spatial memory to tell the story of my life and work over the past few years.
- Things to Keep in Mind When Using Images in Frontend Development Expanding on Jake Archibald's article, this post organizes how modern responsive images should be written: why width/height are still necessary, when to use CSS aspect-ratio, how to choose between AVIF and WebP, and using picture/source/srcset for art direction on mobile devices.
- CSS field-sizing — Auto-resize Form Elements with a Single Line of CSS Previously, auto-resizing a textarea required listening to scrollHeight in JavaScript. With CSS field-sizing: content, a single line replaces it all, supporting textarea, input, and select. This article covers the pain points of older approaches and how to use field-sizing.
- Make Your Link Underlines Look Better: text-underline-offset By default, underlines sit very close to the text. Some designers dislike this look, and personally, I don't think it looks great either.